

One stack, from the carrier to the conversation
A gateway, a media engine, a speech engine, an agent runtime, and a message router. Each is a module that runs in-process, as its own service, or across a fleet.
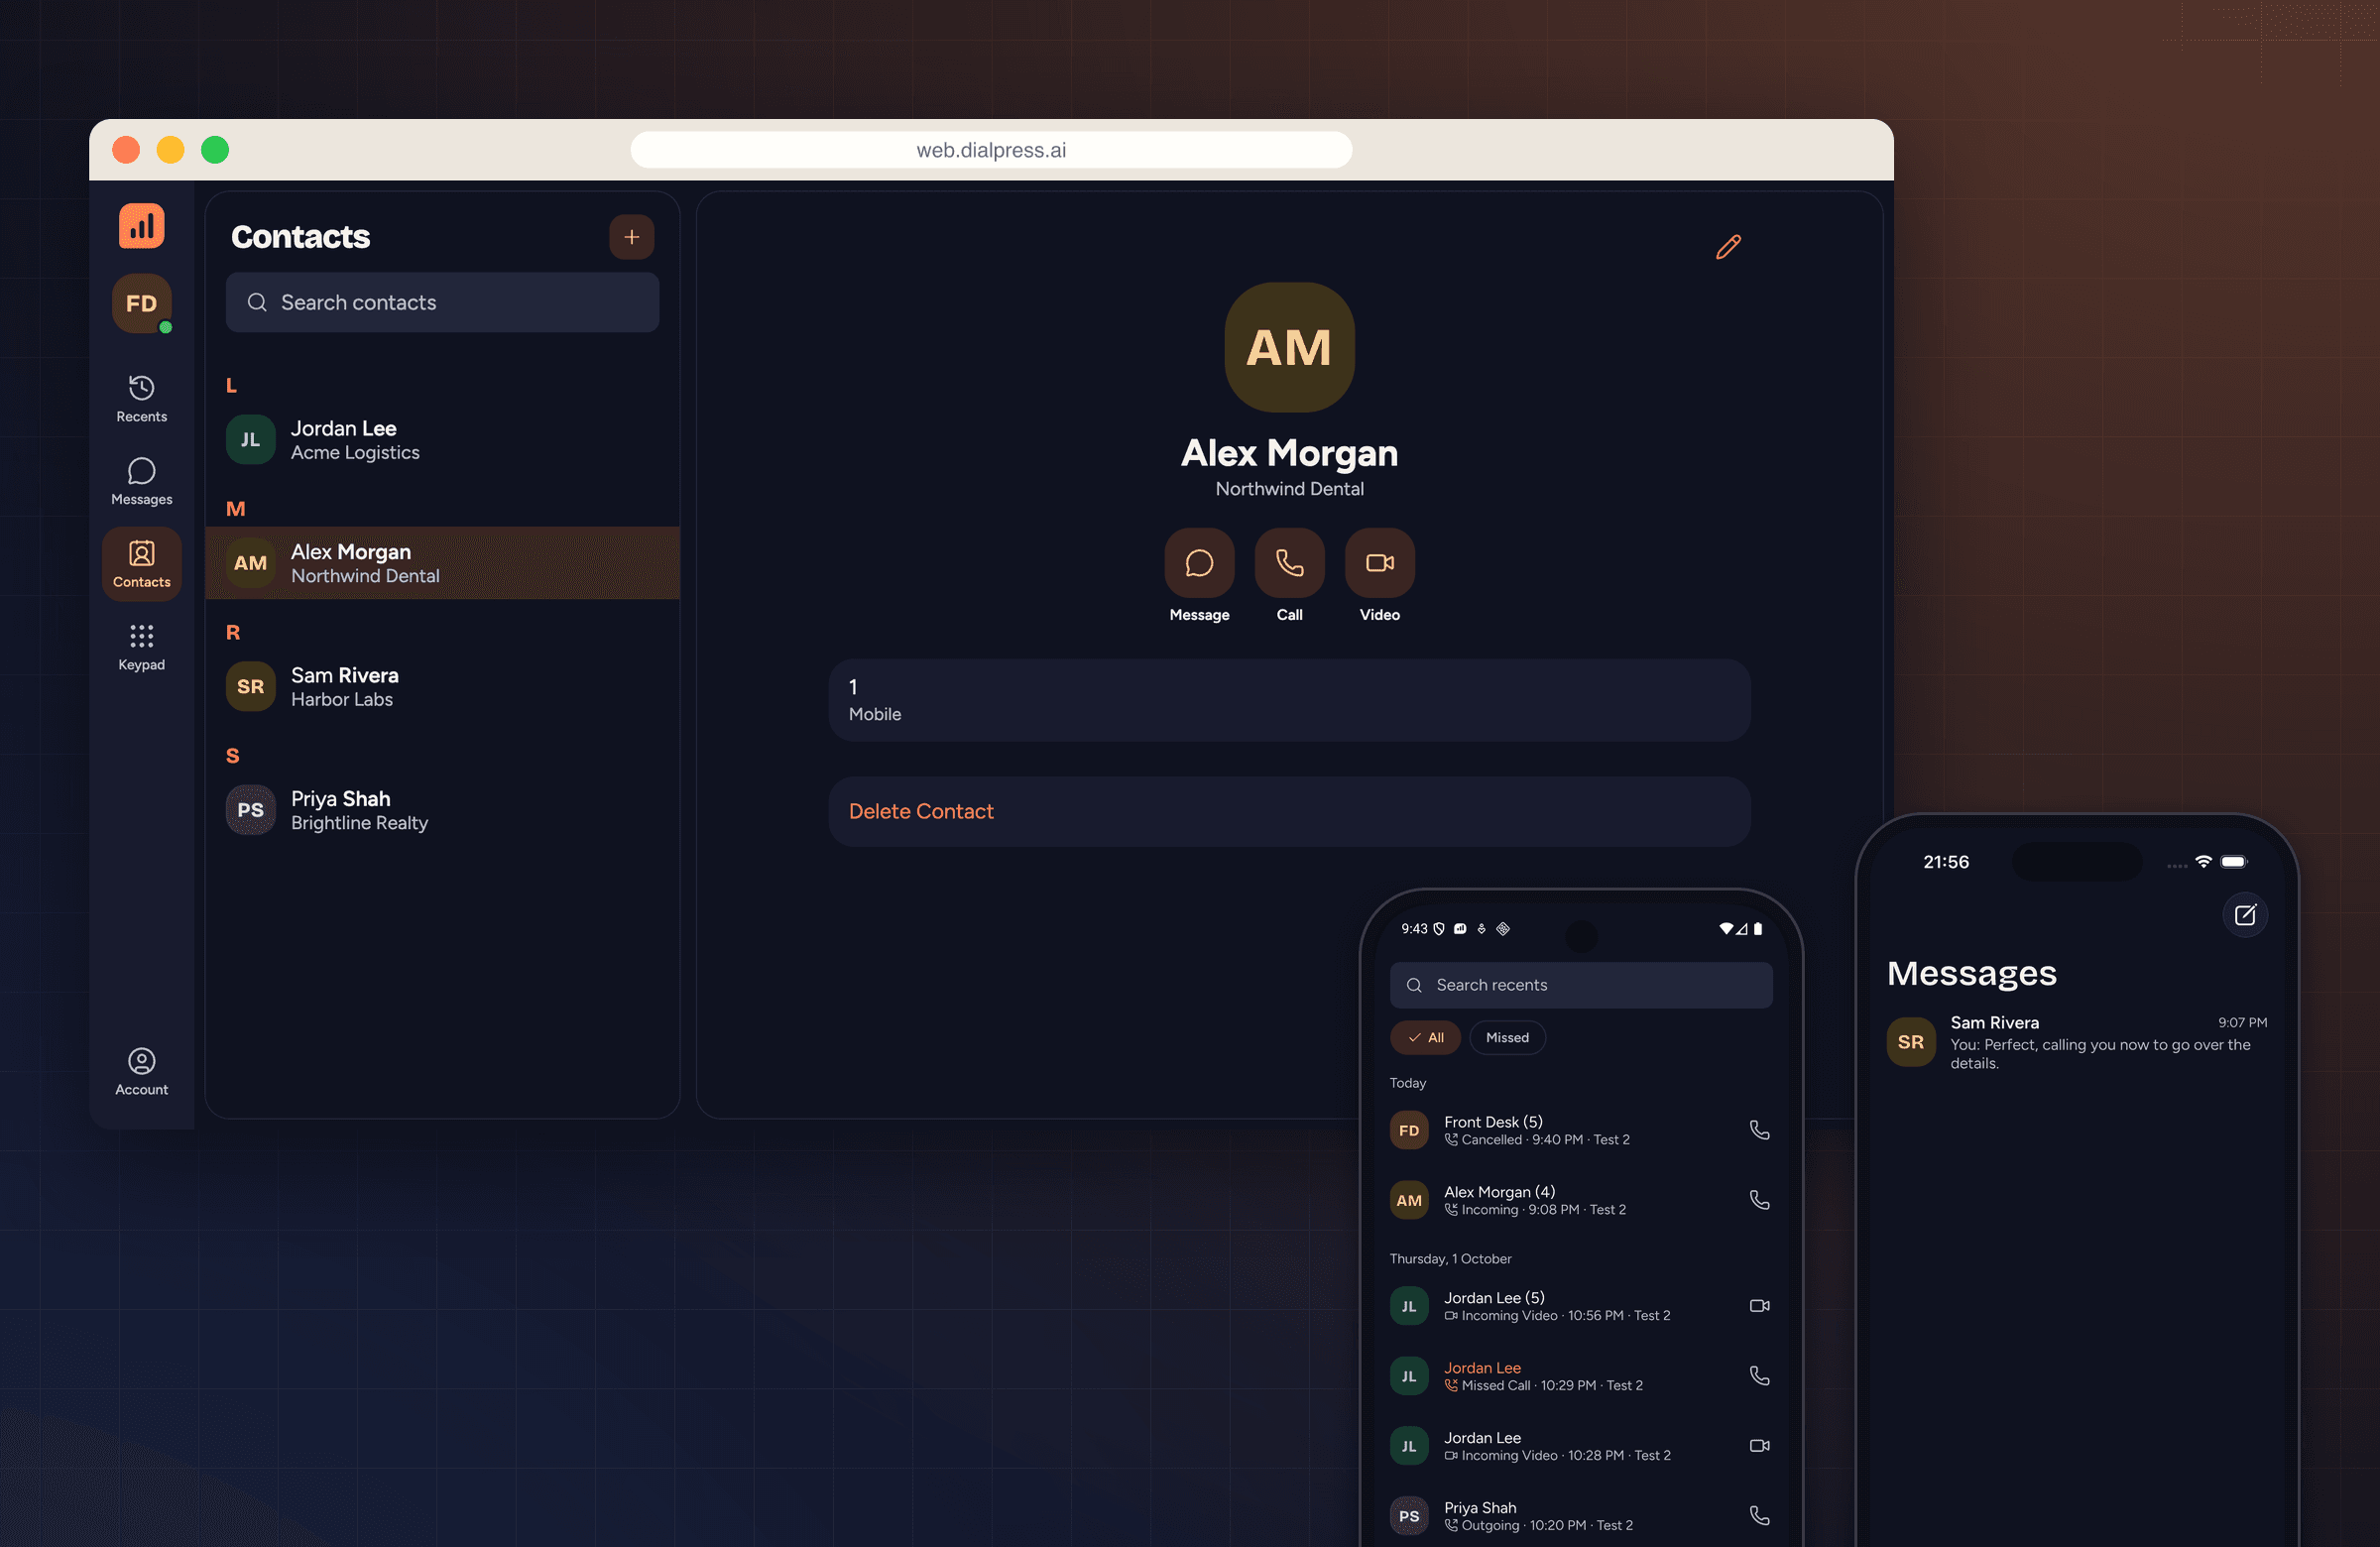
At a glance
One media path
Audio goes from the carrier to speech and the agent without leaving the stack.
Modular
Every module runs in-process, as its own process, or on its own machines.
Programmable
Everything in the dashboard is in the API, the SDK, and the MCP server.
Portable
The same stack runs in DialPress cloud or on your own servers.
Why a voice stack, not a voice API
Most AI voice products are a model attached to someone else’s phone line. When audio arrives late, a number is flagged as spam, or a transfer drops, the model can’t fix it. Those problems live in the network, so that is where DialPress solves them.
The life of a call
What happens between the first ring and the last word.
01
The call arrives
A carrier, a SIP trunk, a desk phone, or a browser sends the call to the gateway. SIP and WebRTC meet there.
02
The dial plan picks a path
Routing flows match on number, time, or digits, and the call lands at a path such as /inbound/15550100 or /ai/front-desk.
03
An app answers
The app that claims the path answers in code: dial a person, play a prompt, or open the call’s audio.
04
Speech and the agent take turns
Caller audio streams to recognition, the agent replies, and text to speech plays back, with barge-in when the caller interrupts.
05
Every step is an event
Call state, keypresses, transcripts, and recordings are published as events and kept with the call.
The primitives
Each one is a page of its own.
Built to scale
Every layer scales on its own. Add capacity where the load is, not everywhere at once.
01
Modular by design
Each module (gateway, speech, agents, messaging, recording) runs in-process, as its own process, or on its own machines over mutual TLS.
02
Horizontal gateways
Run as many gateway instances as you need. Registrations are shared, calls keep dialog affinity, and traffic is spread by policy.
03
GPU-balanced speech
Speech and agent requests go to the least-loaded healthy endpoint that serves the model, weighted per GPU.
04
Autoscaling
On Kubernetes, every module group scales on live metrics and CPU, with bounds you set per module.
05
Zero-drop deploys
Stopping instances drain first: no new calls, live calls finish. Upgrades and scale-downs never cut a caller off.
06
Same code, any size
One binary on a laptop, a Compose stack on a VPS, or a fleet on Kubernetes. Your apps and routes don’t change.
Bring your own models. LLMs from OpenAI or Gemini, speech from open models on your own GPUs or a cloud provider. DialPress routes each request to the endpoint that serves it.
Build on the voice layer.
Full API and SDK access on the 14-day trial.